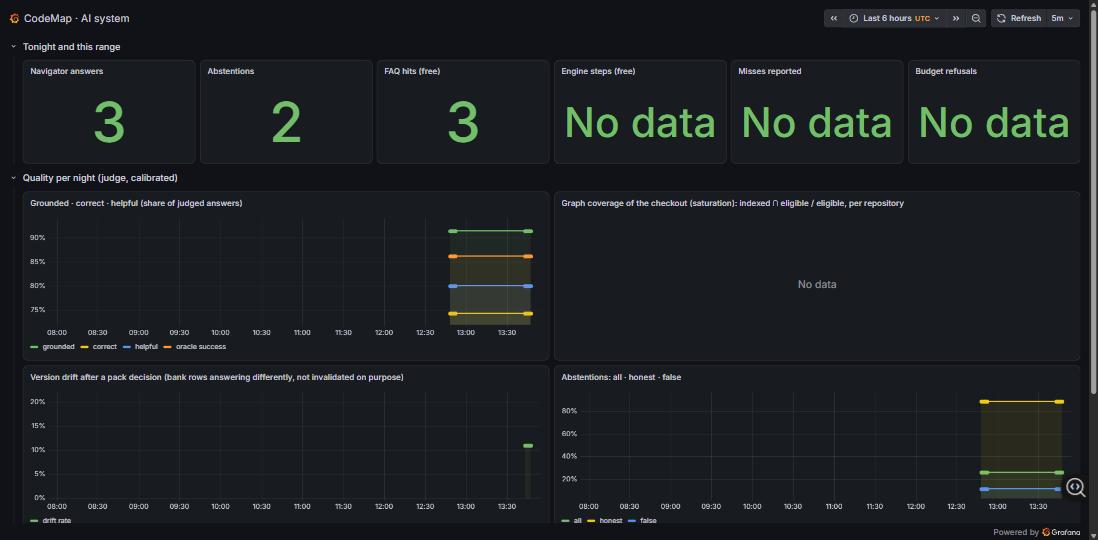
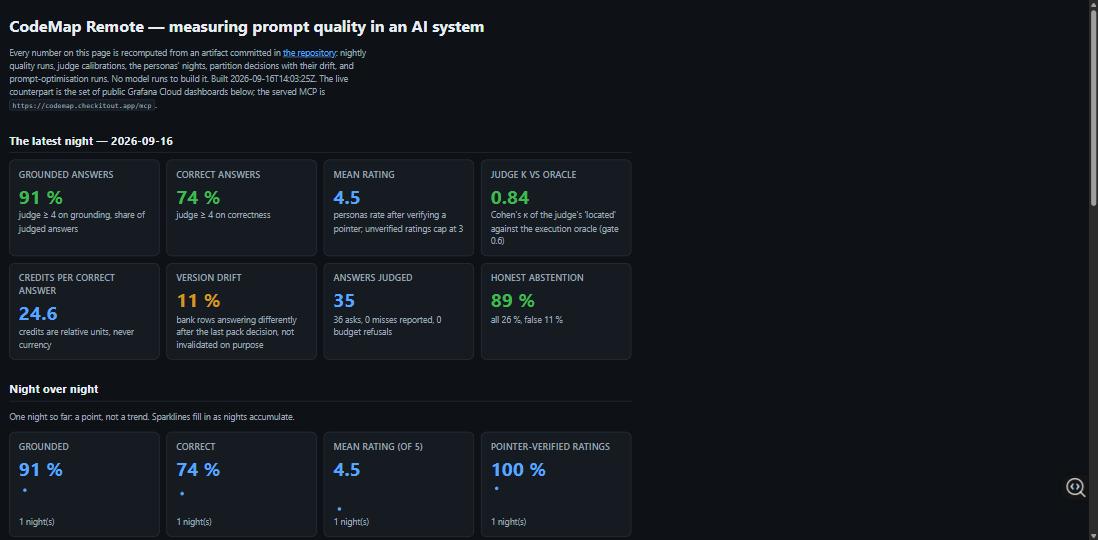
Every number on this page is recomputed from an artifact committed in the repository: nightly quality runs, judge calibrations, the personas' nights, partition decisions with their drift, and prompt-optimisation runs. No model runs to build it. Built 2026-10-22T09:19:15Z. The live counterpart is the set of public Grafana Cloud dashboards below; the served MCP is https://codemap.checkitout.app/mcp.
| persona | conversations | turns | credits | mean rating | misses |
|---|---|---|---|---|---|
haiku-ops | 12 | 229 | 201.7 | 4.7 | 1 |
haiku-pm | 12 | 168 | 206.9 | 4.5 | 2 |
opus-architect | 3 | 74 | 369.1 | 3.6 | 4 |
opus-reviewer | 8 | 222 | 551.3 | 3.5 | 14 |
sonnet-bugfixer | 17 | 265 | 288.0 | 3.3 | 12 |
sonnet-newcomer | 19 | 228 | 226.1 | 4.4 | 2 |
| pack | repo @ head | decision | by | placed | new subsystems | FAQ invalidated | drift | reclued |
|---|---|---|---|---|---|---|---|---|
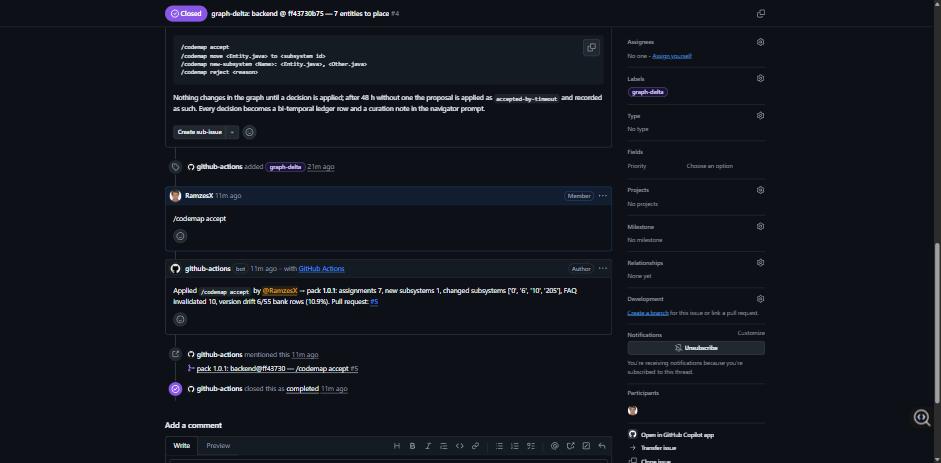
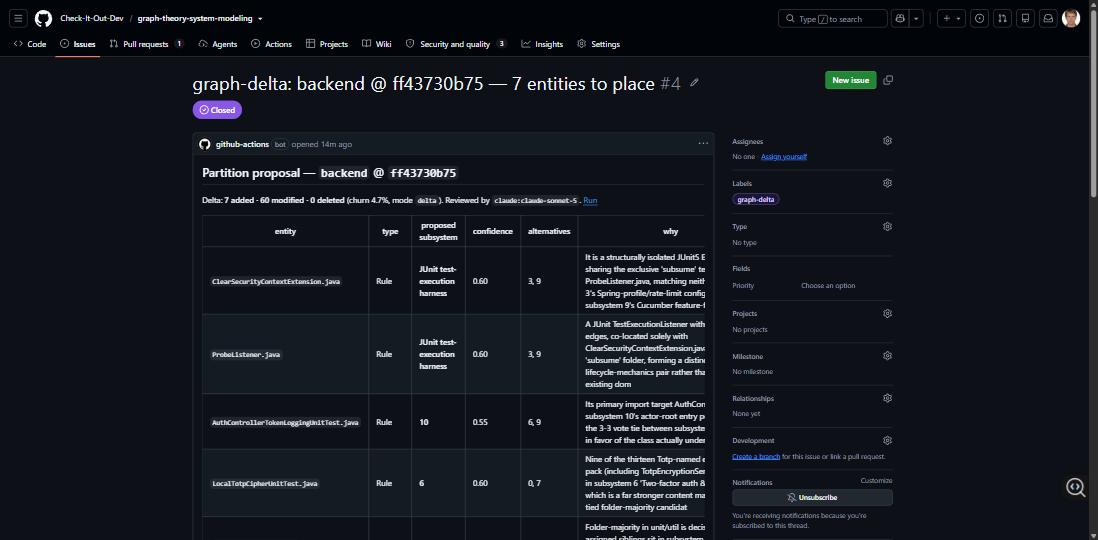
1.0.1 | backend @ ff43730 | accept | RamzesX | 7 | JUnit test-execution harness | 10 | 6/55 (11 %) | — |
1.1.0 | backend+frontend @ ff43730 | accept | RamzesX | 174 | codemap-trajectory-viewer | 12 | 17/54 (31 %) | 0, 3, 4, 6, 8, 9, 10, 11, 16, 170, 171, 174, 175, 176, 178, 205, 206 |
| run | mode | where | seed (val) | best (val) | candidates | metric calls | outcome |
|---|---|---|---|---|---|---|---|
2026-09-16-confirm-candidate | dry-run | box | 1.00 | — | — | 12 | seed measured |
2026-09-16-confirm-seed | dry-run | box | 0.92 | — | — | 12 | seed measured |
2026-09-16-modal-dry | dry-run | modal | 0.67 | — | — | 3 | seed measured |
2026-09-16-noproposal | gepa | box | 0.83 | 0.83 | 1 | 30 | no win — recorded |
2026-09-16b | gepa | box | 0.83 | 1.00 | 3 | 33 | promoted candidate |
| prompt | built | parent | why | gate |
|---|---|---|---|---|
v1 | 2026-09-16 | — | seed: the API navigator prompt's protocol + the big tier's graph lesson, rewritten for pointers | n/a (baseline) |
v2 | 2026-09-16 | v1 | GEPA run 2026-09-16b: val 0.8333333333333334 → 1.0 on 6 examples, 33 metric calls | promoted (0.03 gate) |